


The main reason for using data masking is the protection of sensitive data through substitution or hiding original data values, but without compromising the utility of the data.
Data Masking for Data Protection: Types, Benefits, and Best Practices
Information is the foundation of any business process, but protecting it has become a very difficult challenge. According to IBM’s Cost of a Data Breach Report 2025, the average global cost of a data breach has reached up to $4.9 million. At the same time, businesses need to share their data with analysts, developers, and testing teams.
Data masking helps here a lot. It replaces or masks the sensitive information in order to protect it. This allows teams to work without exposing customer data or any financial information. Data masking reduces security risks and supports compliance efforts.
What is Data Masking?
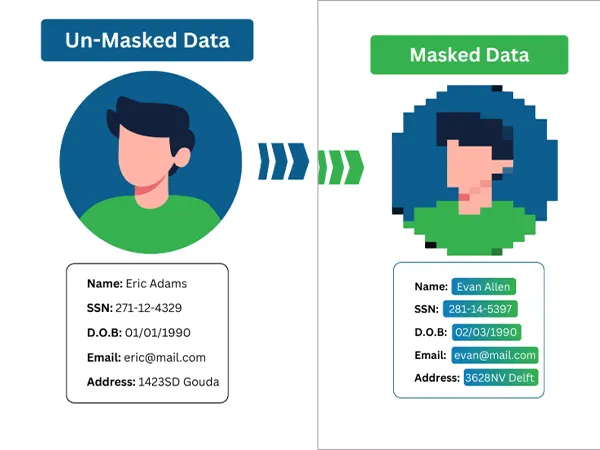
Data masking is a technique of protecting sensitive data by substituting the actual data with some fictional but realistic data. The idea is to preserve the data as usable, but protect the details of it.
For example, instead of using the actual name of the customer, another name can be used, and a credit card number may be masked with a fake but similar number. While working with the data set, no one will understand the difference between the actual information and the fake information.
Unlike encryption, where actual information can be accessed using the right key, data masking is generally used to avoid any kind of unnecessary access to the sensitive data of an organization.
Why Businesses Use Data Masking to Secure Sensitive Information
Organizations use data to conduct day-to-day activities; however, not everybody who uses the data requires access to the actual underlying information. The customer information, employee records, financial data, etc., are frequently duplicated in the development, testing, analysis, and learning environments, and create further security issues.
Data masking helps minimize such concerns by replacing sensitive values in a way that is both useful and realistic from the perspective of business.
Businesses use data masking to –
- Protecting customer and employee information.
- Software development and testing.
- Reducing unnecessary access to sensitive data records.
- Privacy and compliance initiatives.
Common Types of Data Masking Techniques
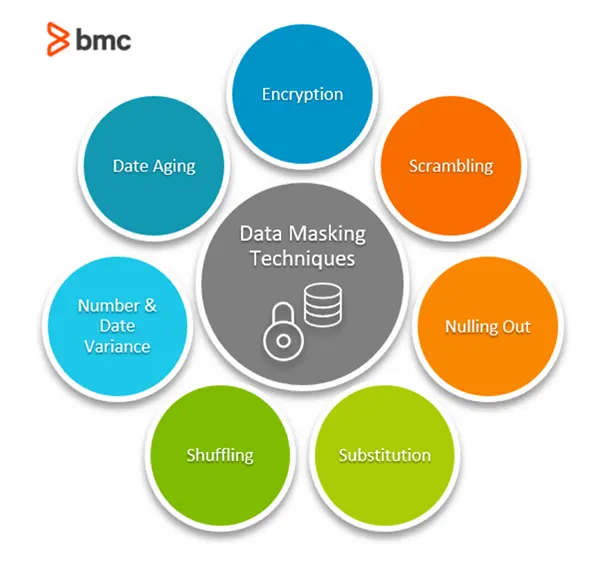
There is no one-size-fits-all technique in masking data. The type of records being handled and how it is intended to be used would determine the appropriate masking technique.
Static Data Masking
Static Data Masking (SDM) is a technique in which a database is duplicated, and sensitive information is masked before distributing the database copy to other teams.
After masking the information, the actual values cannot be recovered in the copied version of the database. As such, static record masking is a common practice when testing software and ensuring quality assurance, as well as training employees, because the figures will be realistic but without customer information. It is also commonly used for mainframe data masking in legacy business systems.
Dynamic Data Masking
DDM operates on an entirely different principle. Rather than altering the data itself, this type of protection regulates how people will perceive information when accessing it. For example, a help desk worker sees the last few numbers of a credit card number, whereas a supervisor or an authorized admin sees all the details, as their position requires.
The actual information stays the same within the database, yet what changes is the presentation of these records to various people. In this way, companies can provide necessary information to employees without disclosing any sensitive figures to everyone.
Tokenization, Substitution, and Data Shuffling
Organizations apply multiple data masking approaches in order to ensure that confidential information remains masked and yet is still usable.
In tokenization, sensitive information is replaced with random tokens that do not have anything to do with the original information. Substitution is another approach where real information is replaced with fictional but realistic figures, like customer names or addresses.
Data shuffling involves changing the position of existing values inside the database in order to provide information that looks realistic.
Where Data Masking Is Used Across Business Systems
Data masking is used widely in different parts of a company, particularly where teams need to use data but do not need to have access to the actual sensitive data.
Software Testing and Development Environments
Both developers and testers may need realistic information when creating additional functionality, testing software applications, and detecting possible problems before releasing software into production.
However, using production figures poses a serious threat as it can lead to disclosure of personal information and additional risks related to security. Data masking becomes the solution as it allows substituting confidential information without losing the realism of the dataset.
As a result, people will be able to work with realistic figures without having real customer information at hand.
Cloud Databases and Data Migration Projects
The transferring of figures from one database or cloud storage to another, or to any new software application, is not always an easy task. The records will travel through several environments and will be processed by various departments.
There will be more chances for exposing confidential records during such a process compared to usual daily tasks. Many companies use the method of data masking before starting the migration process to ensure the security of customers, employees, and other financial information.
Analytics, Reporting, and Third-Party Access
Sometimes, figures are made available to more than just those people working internally. Analysts, consultants, vendors, or even business partners might require access to records for their reports, studies, or other projects.
In most cases, there is no requirement for these parties to know who the clients are. It is the insights that are contained in the important data.
Key Benefits of Data Masking for Security and Compliance
Data masking is not only about hiding sensitive information. It enables businesses to make use of their records with minimized risks associated with the process of sharing and processing big datasets.
Some of the biggest benefits include:
- Reduced exposure risk – The records are safe and protected, even in cases when the data is being processed in non-production environments.
- Compliance purposes – Data masking can be used as one of the ways of protecting private information within the framework of various compliance efforts.
- Safe information sharing – Different teams, including third-party organizations and contractors, can use realistic data sets without having access to customer information.
- Better security practices – Masking helps build another level of security, which will minimize the possible damage caused by insider attacks, human mistakes, and other incidents.
- Data usability – Unlike figure deletion, data masking helps maintain the usability of the records for further analysis and business purposes.
Final Considerations
A wide array of locations handles sensitive information throughout its entire life cycle: applications, testing environments, clouds, analytics software, and external systems. The more locations involved, the greater the chances for the information to get exposed.
By using the methods of data masking, companies can minimize the risk of such incidents without destroying the usability of information. On its own, data masking is not a sufficient security tool; however, if used along with access control, security policies, and regulatory compliance, it can become very helpful.
Frequently Asked Questions
What is the primary purpose of data masking?
How is data masking different from data encryption?
Encryption is the process of encoding data in order to make it unreadable, with the ability to decode the encrypted data with a key. Masking substitutes the sensitive data with fictitious data.
Does data masking impact data quality?
If data masking is done properly, then it does not have any impact on data quality because it maintains the structure and format of the data without affecting its usability.
Which industries can gain the most from data masking?
Those industries that deal with sensitive data in large volumes, including healthcare, financial services, retail, government, and insurance sectors, usually apply data masking techniques.
Related Posts
What Does Air Gapped Mean? How It Works and Why It Matters
An air gapped environment sounds secure simply because it has no internet connection, but keeping data isolated involves more than…
Fix the Data Before You Buy a BI Tool
Most of the growing businesses has one spreadsheet that holds the operation together. It might track orders, jobs, inventory, or…
Best Practices for Confirming Data Sanitization After IT Assets Are Resold
Data sanitization is the permanent, irreversible removal or destruction of data stored on IT hardware and memory devices so that…
How to Protect Business Data From Unwanted Scrapers
Scrapers are a well-known problem for businesses; protecting private records, discouraging unwanted bulk copying, and preserving access are topics one…
Your Email is Data Too: Testing AI Tools That Work Without an Account
People who read about data recovery are most likely to think hard about the place where the files can go.…
UX Design Firm or Full Product Partner: Who Owns the Outcome?
The ownership argument between both kinds of suppliers never ends. The sentence costs nothing to say, but blindly trusting that…
What is BitLocker and How Does It Work?
A stolen laptop can expose far more than the device itself. Your documents, work files, photos, and personal information may…
Beyond the Checkout: 5 Best High-Risk Merchant Account Providers for Online Businesses
Even with polished checkouts, online stores can still have trouble getting secure, suitable payments. The process is more complex than…
The 8 Best Automated Accessibility Testing Tools for Websites
Great copy and sharp design don’t prove that your website is accessible. It’s things like colour contrast, missing alt text,…